
2.快速入门
快速入门
一、工程创建
1.创建一个 JSON 文件
创建工作目录~/sample,并进入,然后创建一个add_custom.json文件,定义一个名为 Add 的算子,该算子定义了两个 fp16 类型的 ND 张量输入,一个输出。
mkdir -p ~/sample && cd ~/sample

cat > add_custom.json << EOF
[
    {
        "op": "AddCustom",
        "input_desc": [
            {
                "name": "x",
                "param_type": "required",
                "format": ["ND"],
                "type": ["fp16"]
            },
            {
                "name": "y",
                "param_type": "required",
                "format": ["ND"],
                "type": ["fp16"]
            }
        ],
        "output_desc": [
            {
                "name": "z",
                "param_type": "required",
                "format": ["ND"],
                "type": ["fp16"]
            }
        ]
    }
]
EOF
2.使用 msopgen 生成工程
确保环境变量已设置(参照上一条笔记),然后运行以下命令:
# 请将 -c 参数中的芯片型号替换为你实际的目标芯片,例如 kirin9020
msopgen gen -i ~/sample/add_custom.json -c ai_core-kirin9020 -out ~/sample/AddCustom
-i:指定 JSON 文件路径。-c:关键参数,格式为ai_core-<soc_version>。<soc_version>需替换为你的芯片型号,如kirin9020、kirin9000等。如果你不确定,可先使用教程示例kirin9020。-out:指定输出工程目录。
基于同系列的AI处理器型号创建的算子工程,其基础能力通用。命令执行完后,会在$HOME/sample目录下生成算子工程目录AddCustom,工程中包含算子实现的模板文件,编译脚本等,如下所示。
AddCustom
├── build_devices.sh // 开发者无需关注,在线编译场景预留,编译device侧交付件脚本
├── build.sh         // 编译入口脚本
├── cmake
│   ├── config.cmake
│   ├── util        // 算子工程编译所需脚本及公共编译文件存放目录
├── CMakeLists.txt   // 算子工程的CMakeLists.txt
├── CMakePresets.json // ** 编译配置项 **
├── framework        // 算子插件实现文件目录,单算子模型文件的生成不依赖算子适配插件,无需关注
├── op_host                      // host侧实现文件
│   ├── add_custom_tiling.h    // ** 算子tiling定义文件 **
│   ├── add_custom.cpp         // ** 算子原型注册、shape推导、信息库、tiling实现等内容文件 **
│   ├── CMakeLists.txt
├── op_kernel                   // kernel侧实现文件
│   ├── CMakeLists.txt
│   ├── add_custom.cpp        // ** 算子核函数实现文件 **
├── scripts                     // 自定义算子工程打包相关脚本所在目录
说明
上述目录结构中标了** **的op_host/add_custom_tiling.h、op_host/add_custom.cpp、op_kernel/add_custom.cpp为后续算子开发过程中需要修改的文件,其他文件无需修改。
3.从WSL终端到可视化操作
在WSL终端中,导航到需要打开的工程目录,比如~/sample/AddCustom,然后使用命令快速跳转到Windows对应目录:
cd ~/sample/AddCustom
explorer.exe .
执行命令后,Windows 的文件资源管理器窗口会立刻弹出,并且自动定位到你刚才所在的 WSL 目录,之后就能使用常用的代码编辑器进行操作了。

二、算子核函数实现
在工程存储目录的AddCustom/op_kernel/add_custom.cpp下面介绍关键实现代码。
算子核函数实现代码的内部调用关系示意图如下。
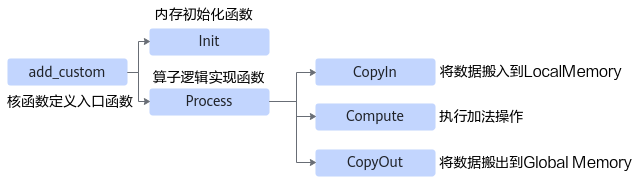
由此可见除了Init函数完成初始化外,Process中完成了对流水任务:搬入、计算、搬出的调用,开发者可以重点关注三个流水任务的实现。
1.进行核函数的定义,并在核函数中调用算子类的Init和Process函数
extern "C" __global__ __aicore__ void add_custom(GM_ADDR x, GM_ADDR y, GM_ADDR z, GM_ADDR workspace, GM_ADDR tiling)
{
    // 获取Host侧传入的Tiling参数
    GET_TILING_DATA(tiling_data, tiling);
    // 初始化算子类
    KernelAdd op;
    // 算子类的初始化函数,完成内存初始化相关工作
    op.Init(x, y, z, tiling_data.totalLength, tiling_data.tileNum);
    // 完成算子实现的核心逻辑
    op.Process();
}
2.定义KernelAdd算子类,其具体成员及成员函数实现如下
#include "kernel_operator.h"
constexpr int32_t BUFFER_NUM = 2;
class KernelAdd {
public:
    __aicore__ inline KernelAdd() {}
    // 初始化函数,完成内存初始化相关操作
    __aicore__ inline void Init(GM_ADDR x, GM_ADDR y, GM_ADDR z, uint32_t totalLength, uint32_t tileNum)
    {
        // 使用获取到的TilingData计算得到singleCoreSize(每个核上总计算数据大小)、tileNum(每个核上分块个数)、singleTileLength(每个分块大小)等变量
        this->blockLength = totalLength / AscendC::GetBlockNum();
        this->tileNum = tileNum;
        this->tileLength = this->blockLength / tileNum / BUFFER_NUM;

        // 获取当前核的起始索引
        xGm.SetGlobalBuffer((__gm__ DTYPE_X*)x + this->blockLength * AscendC::GetBlockIdx(), this->blockLength);
        yGm.SetGlobalBuffer((__gm__ DTYPE_Y*)y + this->blockLength * AscendC::GetBlockIdx(), this->blockLength);
        zGm.SetGlobalBuffer((__gm__ DTYPE_Z*)z + this->blockLength * AscendC::GetBlockIdx(), this->blockLength);
        // 通过Pipe内存管理对象为输入输出Queue分配内存
        pipe.InitBuffer(inQueueX, BUFFER_NUM, this->tileLength * sizeof(DTYPE_X));
        pipe.InitBuffer(inQueueY, BUFFER_NUM, this->tileLength * sizeof(DTYPE_Y));
        pipe.InitBuffer(outQueueZ, BUFFER_NUM, this->tileLength * sizeof(DTYPE_Z));
    }
    // 核心处理函数,实现算子逻辑,调用私有成员函数CopyIn、Compute、CopyOut完成矢量算子的三级流水操作
    __aicore__ inline void Process()
    {
        int32_t loopCount = this->tileNum * BUFFER_NUM;
        for (int32_t i = 0; i < loopCount; i++) {
            CopyIn(i);
            Compute(i);
            CopyOut(i);
        }
    }


private:
    // 搬入函数,完成CopyIn阶段的处理,被核心Process函数调用
    __aicore__ inline void CopyIn(int32_t progress)
    {
        // 从Queue中分配输入Tensor
        AscendC::LocalTensor<DTYPE_X> xLocal = inQueueX.AllocTensor<DTYPE_X>();
        AscendC::LocalTensor<DTYPE_Y> yLocal = inQueueY.AllocTensor<DTYPE_Y>();
         // 将GlobalTensor数据拷贝到LocalTensor
        AscendC::DataCopy(xLocal, xGm[progress * this->tileLength], this->tileLength);
        AscendC::DataCopy(yLocal, yGm[progress * this->tileLength], this->tileLength);
        // 将LocalTensor放入VECIN(代表矢量编程中搬入数据的逻辑存放位置)的Queue中
        inQueueX.EnQue(xLocal);
        inQueueY.EnQue(yLocal);
    }
    // 计算函数,完成Compute阶段的处理,被核心Process函数调用
    __aicore__ inline void Compute(int32_t progress)
    {
        // 将Tensor从队列中取出,用于后续计算
        AscendC::LocalTensor<DTYPE_X> xLocal = inQueueX.DeQue<DTYPE_X>();
        AscendC::LocalTensor<DTYPE_Y> yLocal = inQueueY.DeQue<DTYPE_Y>();
        // 从Queue中分配输出Tensor
        AscendC::LocalTensor<DTYPE_Z> zLocal = outQueueZ.AllocTensor<DTYPE_Z>();
        // 调用Add接口进行计算
        AscendC::Add(zLocal, xLocal, yLocal, this->tileLength);
        // 将计算结果LocalTensor放入到VecOut的Queue中
        outQueueZ.EnQue<DTYPE_Z>(zLocal);
        // 释放输入Tensor
        inQueueX.FreeTensor(xLocal);
        inQueueY.FreeTensor(yLocal);
    }
    // 搬出函数,完成CopyOut阶段的处理,被核心Process函数调用
    __aicore__ inline void CopyOut(int32_t progress)
    {
        // 从VecOut的Queue中取出输出Tensor
        AscendC::LocalTensor<DTYPE_Z> zLocal = outQueueZ.DeQue<DTYPE_Z>();
        // 将输出Tensor拷贝到GlobalTensor中
        AscendC::DataCopy(zGm[progress * this->tileLength], zLocal, this->tileLength);
        // 将不再使用的LocalTensor释放
        outQueueZ.FreeTensor(zLocal);
    }


private:
    // Pipe内存管理对象
    AscendC::TPipe pipe;
    // 输入数据Queue队列管理对象,QuePosition为VECIN
    AscendC::TQue<AscendC::QuePosition::VECIN, 1> inQueueX, inQueueY;
    // 输出数据Queue队列管理对象,QuePosition为VECOUT
    AscendC::TQue<AscendC::QuePosition::VECOUT, 1> outQueueZ;
    // 管理输入输出Global Memory内存地址的对象,其中xGm, yGm为输入,zGm为输出
    AscendC::GlobalTensor<DTYPE_X> xGm;
    AscendC::GlobalTensor<DTYPE_Y> yGm;
    AscendC::GlobalTensor<DTYPE_Z> zGm;
    // 每个核上总计算数据大小
    uint32_t blockLength;
    // 每个核上总计算数据分块个数
    uint32_t tileNum;
    // 每个分块大小
    uint32_t tileLength;
};
三、Host侧算子实现
核函数开发并验证完成后,下一步就是进行Host侧的实现,对应AddCustom/op_host目录下的add_custom_tiling.h文件与add_custom.cpp文件。下面简要介绍下两个文件的关键实现。
1.修改add_custom_tiling.h文件
参考以下代码,在该文件中添加两行代码,进行Tiling参数的定义。
#ifndef ADD_CUSTOM_TILING_H
#define ADD_CUSTOM_TILING_H
#include "register/tilingdata_base.h"
namespace optiling {
BEGIN_TILING_DATA_DEF(AddCustomTilingData)
  // AddCustom算子使用了2个tiling参数:totalLength与tileNum
  TILING_DATA_FIELD_DEF(uint32_t, totalLength);     // 总计算数据量
  TILING_DATA_FIELD_DEF(uint32_t, tileNum);         // 每个核上总计算数据分块个数
END_TILING_DATA_DEF;

// 注册tiling数据到对应的算子
REGISTER_TILING_DATA_CLASS(AddCustom, AddCustomTilingData)
}
#endif // ADD_CUSTOM_TILING_H
2.修改“add_custom.cpp”文件,进行Tiling的实现
修改“TilingFunc”函数,实现Tiling上下文的获取,并通过上下文获取输入输出shape信息,并根据shape信息设置TilingData,序列化保存TilingData,并设置TilingKey。
namespace optiling {
const uint32_t BLOCK_DIM = 1;
const uint32_t TILE_NUM = 8;
static ge::graphStatus TilingFunc(gert::TilingContext* context)
{
    AddCustomTilingData tiling;
    uint32_t totalLength = context->GetInputShape(0)->GetOriginShape().GetShapeSize();
    context->SetBlockDim(BLOCK_DIM);
    tiling.set_totalLength(totalLength);
    tiling.set_tileNum(TILE_NUM);
    tiling.SaveToBuffer(context->GetRawTilingData()->GetData(), context->GetRawTilingData()->GetCapacity());
    context->GetRawTilingData()->SetDataSize(tiling.GetDataSize());
    size_t *currentWorkspace = context->GetWorkspaceSizes(1);
    currentWorkspace[0] = 0;
    return ge::GRAPH_SUCCESS;
}
} // namespace optiling
3.在“add_custom.cpp”文件中实现AddCustom算子的shape推导
Add算子的输出shape等于输入shape,所以直接将输入shape赋给输出shape,当前msOpGen工具生成的代码“InferShape”函数无需修改。
4.修改“add_custom.cpp”文件中的算子原型注册,此函数为入口函数
注意替换芯片型号!
namespace ops {
class AddCustom : public OpDef {
public:
    explicit AddCustom(const char* name) : OpDef(name)
    {
        // Add算子的第一个输入
        this->Input("x")
            .ParamType(REQUIRED)    // 代表输入必选
            .DataType({ ge::DT_FLOAT16, ge::DT_FLOAT, ge::DT_INT32 })   // 输入支持的数据类型
            .Format({ ge::FORMAT_ND, ge::FORMAT_ND, ge::FORMAT_ND });   // 输入支持的数据格式
        // Add算子的第二个输入
        this->Input("y")
            .ParamType(REQUIRED)
            .DataType({ ge::DT_FLOAT16, ge::DT_FLOAT, ge::DT_INT32 })
            .Format({ ge::FORMAT_ND, ge::FORMAT_ND, ge::FORMAT_ND });
        this->Output("z")
            .ParamType(REQUIRED)
            .DataType({ ge::DT_FLOAT16, ge::DT_FLOAT, ge::DT_INT32 })
            .Format({ ge::FORMAT_ND, ge::FORMAT_ND, ge::FORMAT_ND });
        // 关联InferShape函数
        this->SetInferShape(ge::InferShape);
        // 关联Tiling函数
        this->AICore()
            .SetTiling(optiling::TilingFunc);
        // 注册算子支持的AI处理器型号,请替换为实际支持的AI处理器型号,如kirin9020
        this->AICore().AddConfig("kirinxxx");
    }
};
// 结束算子注册
OP_ADD(AddCustom);
} // namespace ops
四、算子工程编译部署
编译AddCustom工程,生成自定义算子安装包,并将其安装到算子库中。
1.编译自定义算子工程,构建生成自定义算子包
在算子工程AddCustom目录下执行如下命令,进行算子工程编译。
./build.sh

2.自定义算子安装包部署
在执行编译的同时,会将交付件安装到DDK安装目录下的指定目录。
~/ddk/tools/platform
查看部署后的目录结构,如下所示:
platform                            // 平台插件目录
├── kirin9020                       // Kirin AI处理器类型
│   ├── config
│   │   └── npu_custom_opinfo.json  // 算子信息库
│   ├── lib64
│   │   └── libcustom_op.so         // host侧二进制文件
│   ├── ops
│   │   └── impl
│   │       ├── custom              // kernel交付件
│   │       │   ├── add_custom.cpp
│   │       │   ├── add_custom.py
│   │       │   └── op_proto.h
│   │       └── impl
│   └── simulator
└── README.md

 浙公网安备 33010602011771号