AMP
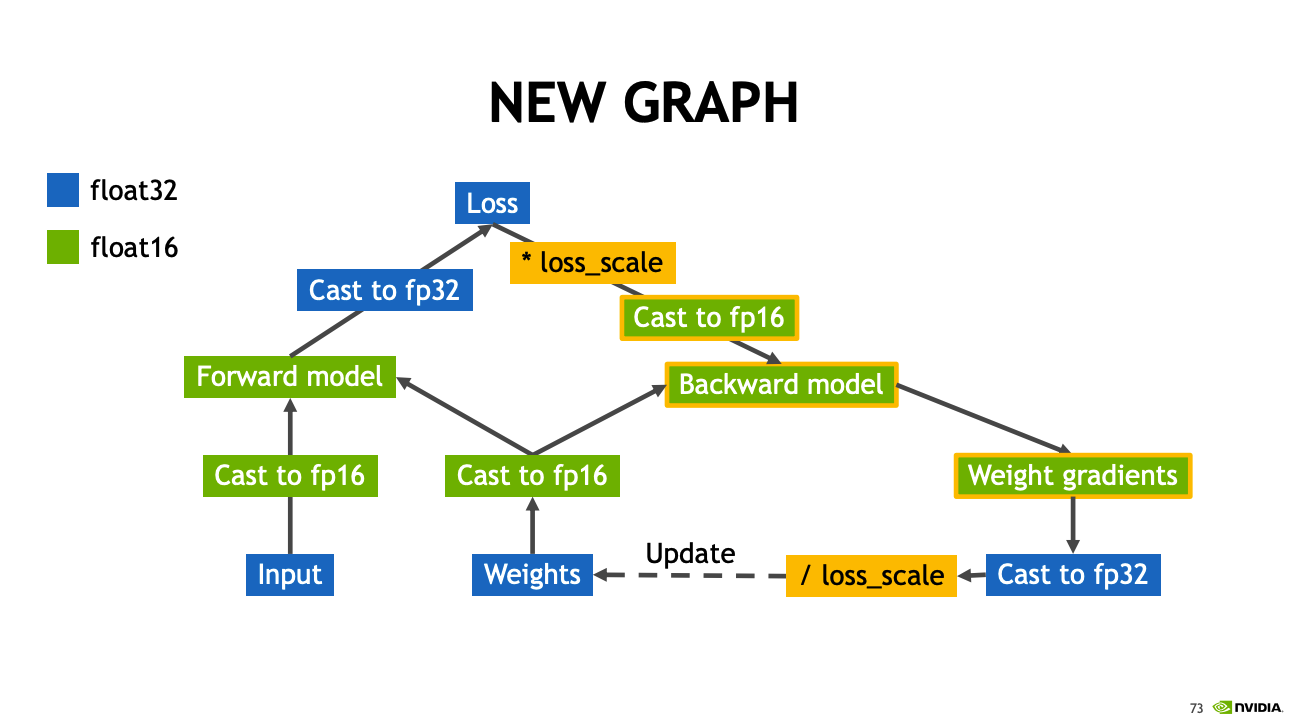
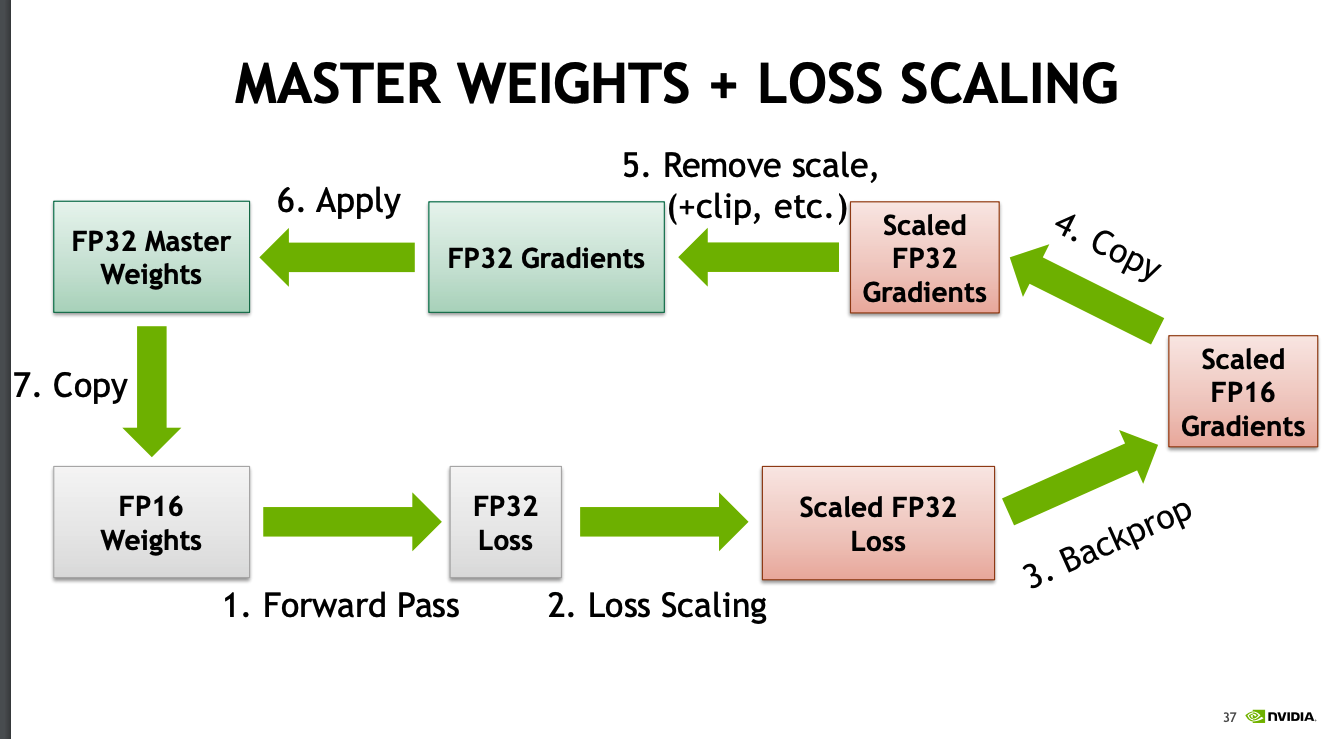
autocast op reference
Op Eligibility
Ops that run in float64 or non-floating-point dtypes are not eligible, and will run in these types whether or not autocast is enabled.
Only out-of-place ops and Tensor methods are eligible. In-place variants and calls that explicitly supply an out=... Tensor are allowed in autocast-enabled regions, but won’t go through autocasting. For example, in an autocast-enabled region a.addmm(b, c) can autocast, but a.addmm_(b, c) and a.addmm(b, c, out=d) cannot. For best performance and stability, prefer out-of-place ops in autocast-enabled regions.
Ops called with an explicit dtype=... argument are not eligible, and will produce output that respects the dtype argument.
CUDA Ops that can autocast to float16
__matmul__, addbmm, addmm, addmv, addr, baddbmm, bmm, chain_matmul, multi_dot, conv1d, conv2d, conv3d, conv_transpose1d, conv_transpose2d, conv_transpose3d, GRUCell, linear, LSTMCell, matmul, mm, mv, prelu, RNNCell
CUDA Ops that can autocast to float32
__pow__, __rdiv__, __rpow__, __rtruediv__, acos, asin, binary_cross_entropy_with_logits, cosh, cosine_embedding_loss, cdist, cosine_similarity, cross_entropy, cumprod, cumsum, dist, erfinv, exp, expm1, group_norm, hinge_embedding_loss, kl_div, l1_loss, layer_norm, log, log_softmax, log10, log1p, log2, margin_ranking_loss, mse_loss, multilabel_margin_loss, multi_margin_loss, nll_loss, norm, normalize, pdist, poisson_nll_loss, pow, prod, reciprocal, rsqrt, sinh, smooth_l1_loss, soft_margin_loss, softmax, softmin, softplus, sum, renorm, tan, triplet_margin_loss
reference:
https://pytorch.org/docs/master/amp.html#autocast-op-reference
https://on-demand.gputechconf.com/gtc-taiwan/2018/pdf/5-1_Internal%20Speaker_Michael%20Carilli_PDF%20For%20Sharing.pdf
https://nvlabs.github.io/eccv2020-mixed-precision-tutorial/
https://zhuanlan.zhihu.com/p/79887894

 浙公网安备 33010602011771号