
使用python获取知乎**话题下的所有回答,并统计后发布。
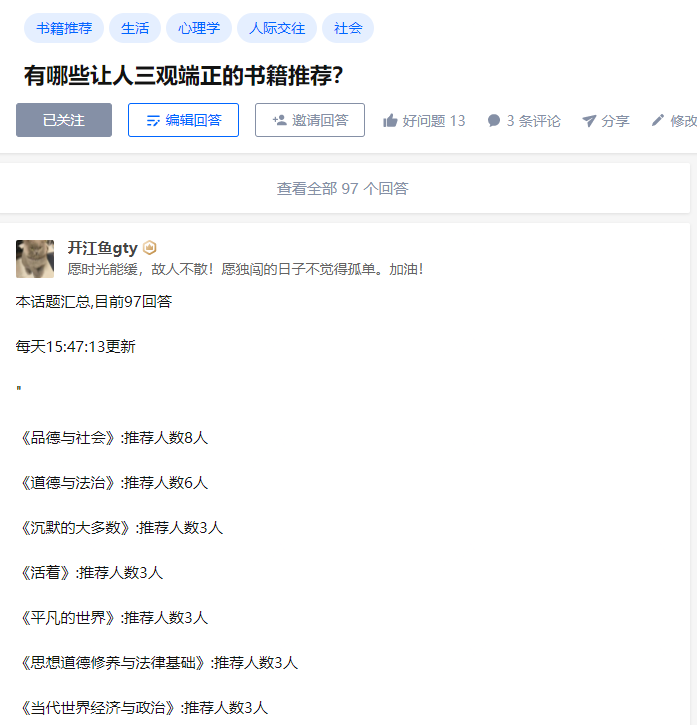
第一步:获取话题需要的url需要,并向上取整
 for idx in range(0,math.ceil(totals/5)):
        url = f"https://www.zhihu.com/api/v4/questions/29114634/answers?include=data%5B%2A%5D.is_normal%2Cadmin_closed_comment%2Creward_info%2Cis_collapsed%2Cannotation_action%2Cannotation_detail%2Ccollapse_reason%2Cis_sticky%2Ccollapsed_by%2Csuggest_edit%2Ccomment_count%2Ccan_comment%2Ccontent%2Ceditable_content%2Cattachment%2Cvoteup_count%2Creshipment_settings%2Ccomment_permission%2Ccreated_time%2Cupdated_time%2Creview_info%2Crelevant_info%2Cquestion%2Cexcerpt%2Cis_labeled%2Cpaid_info%2Cpaid_info_content%2Crelationship.is_authorized%2Cis_author%2Cvoting%2Cis_thanked%2Cis_nothelp%2Cis_recognized%3Bdata%5B%2A%5D.mark_infos%5B%2A%5D.url%3Bdata%5B%2A%5D.author.follower_count%2Cvip_info%2Cbadge%5B%2A%5D.topics%3Bdata%5B%2A%5D.settings.table_of_content.enabled&limit=5&offset={idx*5}&platform=desktop&sort_by=default"
        url_list.append(url)e
第二步:使用多线程,批量请求所有话题内容,获取到【“书籍”】列表
#创建十个个线程作为生产者,请求
    for x in range(10):
        product = threading.Thread(target=get_pic_url)
        product.start()
#生产者:请求url,获取所有书籍list
def get_pic_url():
    while True:
        glock.acquire()
        if len(url_list) == 0:
            glock.release()
            break
        else:
            page_url = url_list.pop()
            glock.release()
            res = urllib.request.Request(page_url,headers=headers)#请求
            res2 = urllib.request.urlopen(res).read().decode("utf-8")#获取html
            objContent = json.loads(res2)['data']#获取数据data
            ddd = re.compile(r'《.*?.》')#正则《》包裹的书籍
            glock.acquire()
            for rel in objContent:
                result = ddd.findall(str(rel['content']))
                for gtygty in result:
                    if len(gtygty)<30: #《》如果小于30个字符,就是正常书籍
                        contentList.append(gtygty)
                    else:
                        zz = re.compile(r'>.*?.<')#带有超链接的,则在处理一遍
                        hrefcontent = zz.findall(gtygty)
                        data = str(hrefcontent).replace(">","《",1).replace("<","》",1)
                        contentList.append(data[2:-2])
            glock.release()
第三:获取到图书后,统计每本书出现的次数
# 统计书籍出现的频率
def download_picture():
    ifStop=0
    submit = []
    while True:
        glock.acquire()
        if len(contentList) ==0:
            glock.release()
            ifStop +=1
            if ifStop == 2:
                y2 = {k: v for k, v in sorted(tongjicishu.items(), key=lambda item: item[1], reverse=True)}
                for key in y2.keys():
                    submit.append("<p>"+ key+ ":推荐人数"+str(y2[key])+"人</p>")
                return ''.join(submit)
                break
            else:
                continue
        else:
            url = contentList.pop()
            glock.release()
            #修改文件名
            if tongjicishu.__contains__(url) :
                tongjicishu[url]=tongjicishu[url]+1
            else :
                tongjicishu[url]=1
第四步:调用download_picture函数,获取到可发布的带标签的content,并发布
putcontent = download_picture()
submitPut("<p>本话题汇总,目前"+str(totals)+"回答</p>"+"<p>每天"+time.strftime('%H:%M:%S')+"更新</p>"+json.dumps(putcontent,ensure_ascii=False))
def submitPut(putcontent):
    putUrl = "https://www.zhihu.com/api/v4/answers/2342429808?include=is_visible%2Cpaid_info%2Cpaid_info_content%2Cadmin_closed_comment%2Creward_info%2Cannotation_action%2Cannotation_detail%2Ccollapse_reason%2Cis_normal%2Cis_sticky%2Ccollapsed_by%2Csuggest_edit%2Ccomment_count%2Ccan_comment%2Ccontent%2Ceditable_content%2Cvoteup_count%2Creshipment_settings%2Ccomment_permission%2Ccreated_time%2Cupdated_time%2Creview_info%2Crelevant_info%2Cquestion%2Cexcerpt%2Cattachment%2Crelationship.is_authorized%2Cvoting%2Cis_thanked%2Cis_author%2Cis_nothelp%2Cis_recognized%2Cis_labeled%3Bmark_infos%5B*%5D.url%3Bauthor.vip_info%2Cbadge%5B*%5D.topics%3Bsettings.table_of_content.enabled"
    data = {
           "content":putcontent,
           "reshipment_settings":"disallowed",
           "comment_permission":"all",
           "reward_setting":{"can_reward":False,"tagline":""},
           "disclaimer_status":"close",
           "disclaimer_type":"none",
           "commercial_report_info":{"is_report":False},
           "is_report":False,
           "push_activity":True,
           "table_of_contents_enabled":False,
           "thank_inviter_status":"close"
           }
    datascontent=json.dumps(data).encode('utf8')
    # data = urllib.parse.urlencode(formData).encode("utf-8")
    putres = urllib.request.Request(putUrl,data=datascontent,headers=headers,method='PUT')#请求
    putres2 = urllib.request.urlopen(putres).read().decode("utf-8")#获取html

 浙公网安备 33010602011771号